
Image Details
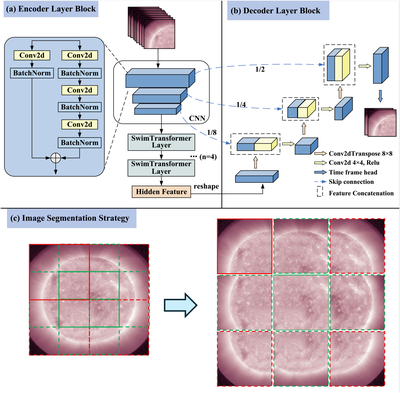
Caption: Figure 1.
Overview of SwinTransUnet architecture. (a) The input image sequence consisting of Tx frames is first processed by a series of CNN layers, followed by four Swin transformer layers. (b) The resulting latent-space representation is then decoded to reconstruct the image sequence. Finally, a time-frame head is applied to specify the number of output frames. The blue joined part comes from the CNN layer of (a). (c) Image segmentation strategy. Each 4K image is segmented into nine overlapping 2K segments (with a 1024 pixel overlap).
Other Images in This Article
Copyright and Terms & Conditions
© 2026. The Author(s). Published by the American Astronomical Society.

Copyright ©
2026 Astronomy Image Explorer. All Rights Reserved.
