
Image Details
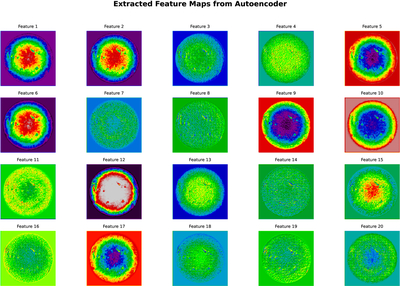
Caption: Figure 4.
Spatial feature maps produced by the convolutional AE encoder for a representative training frame. Each panel shows one of the 32 channels of the 128 × 128 × 32 bottleneck representation; spatial global-average pooling of these 32 maps yields the 32-dimensional feature vector zt (Equation (7)) carried to the LSTM.
Other Images in This Article
Show More
Copyright and Terms & Conditions
© 2026. The Author(s). Published by the American Astronomical Society.

Copyright ©
2026 Astronomy Image Explorer. All Rights Reserved.
